 UseAIHere
Course page: Lecture 1 of the 2026 Generative Software Engineering course at Nanjing University
1. Why this course is appearing now
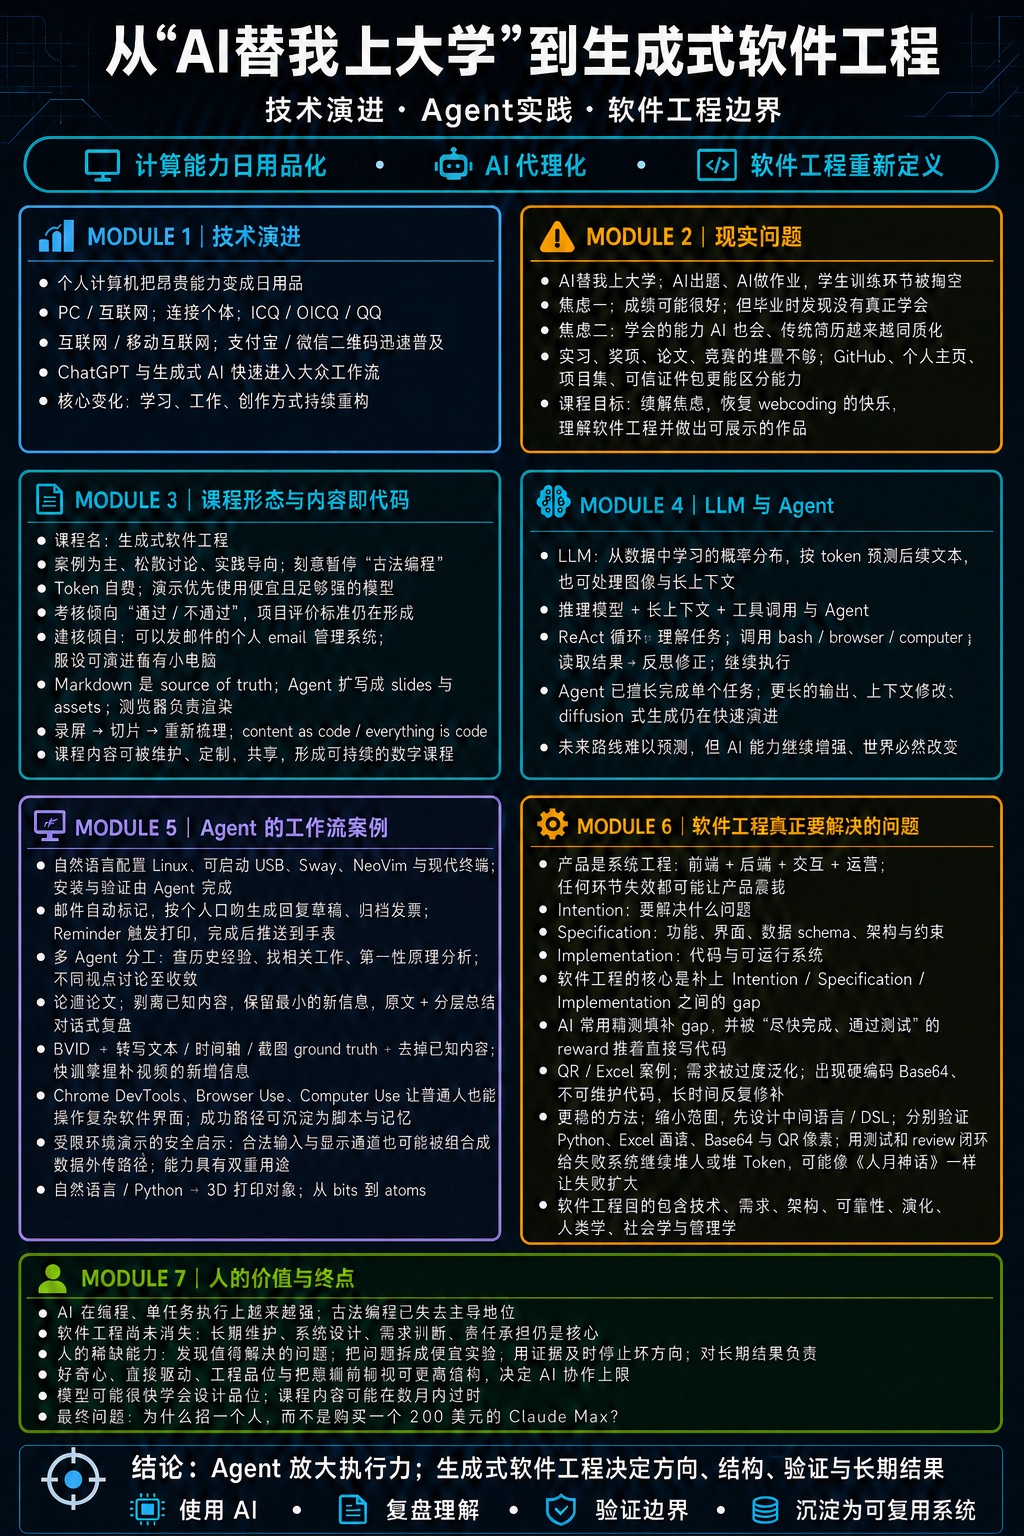
The lecture starts from a practical problem: computers are going through another round of capability democratization, while university education, the way people learn, and the way people work have not fully adapted to it.
The same thing happens again and again in the history of computing: a capability that was expensive and scarce, available to only a few people, becomes something ordinary people use every day. Personal computers brought computing power into personal life. The internet connected people, and mobile internet put payments, communication, and services on everyone's phone. Generative AI compresses text generation, image generation, code writing, information processing, and software operation into natural-language interaction.
The class uses the evolution of ICQ, OICQ, and QQ to illustrate the sense of connection in the early internet: you could reach someone at the other end of the world at random, even if the two of you differed completely in language and experience. Mobile payments show another kind of change: QR codes entered everyday scenes such as vegetable markets in a very short time, and changed how people complete transactions. Generative AI is spreading faster still, and it has already begun to change how people learn, work, and create.
The dilemma of "letting AI do my degree for me"
When teachers use AI to write exam questions and students use AI to do homework, the course can still complete its assessments, but the students may not get trained. The teaching loop looks normal, and the part where students themselves gain ability from the problems is missing.
This shift brings several specific anxieties:
- Grades can be very good, and you can still find at graduation that you never really mastered the ability to solve problems;
- AI can already do many of the skills you worked hard to learn;
- Huge numbers of résumés stack up internships, awards, papers, and competitions, which makes people harder and harder to tell apart;
- If a résumé has no GitHub, personal homepage, preprints, runnable projects, or other verifiable work, the experiences on paper can hardly demonstrate real ability.
The class gave an example of a résumé that looks perfect: papers and experience on the page, but no code repository, no personal homepage, nothing that would let a reader verify anything further. What the résumé leaves out is evidence of real work. Generative AI makes textual packaging easier, and makes "looking excellent" less scarce.
The course therefore aims at two things: the ability to use AI to produce real work, and the ability to understand software engineering well enough to judge the quality of results and leave verifiable outcomes behind.
2. Course positioning: generative software engineering
The course is still a software engineering course, with generative AI and agents added to the process that produces the software.
Software engineering is not the same thing as writing the code out. The more fundamental questions are how to keep software from failing, and how to turn a requirement into software that can be delivered, verified, and maintained.
The course is case-led, with practice first and discussion kept loose. Cases in class include configuring an operating system, handling email, reading papers, analyzing videos, operating a browser, building Excel tools, and designing maintainable software architecture. Traditional "old-school programming" is no longer the center of the course; the focus shifts to describing problems, directing agents, verifying outputs, and settling one-off successes into systems that stay reusable.
The course also discussed several practical constraints:
- Token costs need to be brought into the workflow; demos can prefer models that are cheaper, faster, and capable enough;
- A model should not be treated as an absolutely reliable black box; important results still need checking;
- The course design leans toward evaluating projects as pass / fail, but the specific judging criteria are still taking shape;
- One executable project direction is a personal email management system that can send and receive mail, handle replies, and keep running long term on a small computer;
- A project's value is not confined to its grade: what matters is whether it ends up as a work that is accessible, explainable, and reproducible.
Content as code
The courseware shown in class is itself a case of generative software engineering. The Markdown lecture notes are treated as the source of truth; agents expand the notes into slides and image assets, and the browser renders those into the final courseware. Many images and page elements in the courseware are generated by AI, and the content is adjusted further through rounds of prompting, different agents, and blind review.
This approach splits one lecture into several objects that can be processed further:
- The Markdown lecture notes written in advance;
- The in-class explanation and spontaneous discussion;
- The recorded complete course;
- Knowledge clips produced by slicing, review, and recombination;
- A digital course that can be maintained, customized, and shared afterward.
The slogan "content as code", or "everything is code", asks for content with a clear origin, structure, and generation process, in a form that can be maintained. A course can then be revised, combined, and reused like software, and even maintained further by different people.
3. From large language models to agents
The class builds an intuition a user can hold before it goes anywhere near the engineering details of training models.
A large language model can be understood as a probability distribution learned from a large amount of data. Given a piece of context, it keeps predicting the tokens that follow; the output looks like a continuous article, code, or answer, but it is the composition of many predictions. A model can handle very long text, and different forms of input such as images, but it is not automatically a reliable software engineer.
Agents appear once the model has longer context, stronger reasoning, and the ability to call tools. An agent can:
- Read the task and the current environment;
- Invoke tools such as bash, the browser, or computer control;
- Observe the results the tools return;
- Judge whether the current path is reasonable;
- Modify the plan and keep executing;
- End the task after verification passes.
This is the ReAct-style loop shown repeatedly in class: the model's output can trigger a program, the program's results are fed back into the model's context, and the model continues to act accordingly. A complex task therefore becomes several rounds of observation, action, and correction rather than one generation.
The first step in using agents is to hand one a clear task and let it start working, not to learn how to train a model. Configuration files such as AGENTS.md in a project can provide standing background, roles, and constraints, and you can learn an agent's capability boundaries gradually through follow-up questions, inspection, and feedback. The judgment offered in class: imagination, the ability to describe requirements, and the ability to verify results determine how far an agent can be used.
4. What agents can do: from personal environments to knowledge workflows
4.1 Configuring the local system in natural language
The class showed a local working environment that was put together with an agent's help. A bootable Linux system was placed on a USB device; the window manager, terminal, NeoVim, and command-line tools were customized, with the interface and way of operating optimized around the class demonstration.
Configuring an environment like that used to mean consulting large amounts of documentation, understanding configuration files, repeated trial and error, and handling compatibility issues item by item. Now you can describe the goal in natural language and let the agent check the system state, install components, modify configuration, and verify the results. The agent can also replace ordinary commands with tools better suited to daily use, and make unified adjustments to terminal output, window layout, and keyboard shortcuts.
What changes here is how knowledge is used rather than whether people still need it. You need to know what kind of system you want, know which results are worth accepting, and be able to spot errors and ask the agent to re-check; the specific configuration details can be handed to the agent.
4.2 Handing daily tasks to a personal agent
Another case is a personal email workflow. The system stores the emails and replies it has processed in the past, so when a new email arrives the agent can run a chain of consecutive actions:
- Label the email's status automatically;
- Generate reply drafts according to the established tone;
- Recognize invoices and other materials in attachments;
- Save important attachments to the designated archive location;
- Receive tasks from Reminders;
- Call the printer to finish printing;
- Push a notification to the watch when done.
No single action in a flow like this is complicated. What matters is that several tools run together as one continuous workflow: email, database, file archiving, Reminders, the printer, and notification devices form a personal automation system.
The class also drew the boundary. Daily tasks can be handed to an agent, as long as the task is trustworthy enough and the risk acceptable, and important results should still go through confirmation. An agent being able to operate the computer does not mean every operation should be authorized without conditions.
4.3 Using multiple agents to speed up reading books, papers, and videos
Agents change how knowledge is acquired as well as how code gets written.
When you read a paper, different agents can each take on a different task: looking back at humanity's existing knowledge and historical cases, searching for related work, analyzing the problem from first principles, or raising challenges from different positions. After the agents form different views, they discuss; the lead agent hands the disagreements back to them for handling, until relatively stable conclusions are reached.
Reading this way strips away the parts you already know, extracts what is genuinely new, and then continues the conversation with the original text, layered summaries, and questions. For a very long paper, once the known background and the formalistic groundwork are compressed, the main contributions, assumptions, and limitations left over are easier to locate.
Watching videos can follow a similar process:
- Capture the complete content and organize it into workable material;
- Generate the transcript and the image-text timeline;
- Keep screenshots at necessary points as ground truth;
- Let the agent identify already familiar content;
- Keep only the new ideas, cases, and methods;
- Return to the original video with the summary to verify.
What you get is video turned from a consume-once medium into knowledge material that can be searched, reviewed, and reorganized.
4.4 Browser and computer-use capabilities
The browser is an extremely complex software engineering product. Chrome DevTools provides development interfaces for page structure, network requests, script execution, and state observation. In the past, only developers used these capabilities systematically; agents can put part of them in ordinary users' hands.
Typical operations mentioned in class include opening developer tools, observing the page and network requests, reading request headers and cookies, copying browser requests into cURL commands, and continuing to process data while preserving the current state. The class also showed the idea of running an Android interface in the browser: once an app's interface elements, text, and coordinates are extracted, display and interaction can happen through the browser.
When an agent operates a web page, it may try one approach first, find that directly injecting events does not work, then switch to real clicks or another viable path. A failure does not have to end the task; the agent can observe the failure result, choose tools again, and keep trying.
A successful operation path can also be saved as a script or a memory. Once the agent has done an exploratory operation, repeated tasks can become deterministic automated flows. Browser operations, page state, scripts, and memories can then be combined into larger personal workflows.
4.5 The stronger the capability, the more the security boundary matters
The restricted-environment case in class shows the dual use of agent capability: a machine can allow files to enter while forbidding files from leaving directly, and combining legitimate input, display, and interaction channels can still produce a path for data to get out.
The QR-code animation and Excel formula demos were not an attack tutorial. They showed that a security boundary cannot rely only on "forbidding program installation" or "forbidding file copying". When an agent can operate the browser, desktop, spreadsheets, the printer, and other devices, channels that used to be separate can be recombined. Software engineering design has to consider function, permission, observability, and misuse risk at the same time.
4.6 From bits to atoms
At the end, the class widened the view from on-screen digital content to the real world: natural language can drive a Python program, and the Python program can in turn produce 3D-printed objects. Videos, papers, slides, code, and physical objects can all sit on the same chain from content to code to execution.
"From bits to atoms" describes something that already happens: as long as a digital object can be described by code, an agent can take part in the conversion from intent to physical object.
5. Software engineering has to close the "gap"
AI can complete many local tasks, but a usable product is not the sum of local tasks.
For example, a food-delivery system contains frontend, backend, interaction, data, deployment, and operations at the same time. AI can help design pages, write interfaces, generate the database schema, or propose operations plans separately, but as long as one piece does not match the others, the whole product may be unusable. Product development is systems engineering, and organizing these local capabilities matters more than generating a piece of code.
5.1 Three spaces
The class uses three spaces to describe the conversion process of software from idea to product:
| Space | Core question | Typical content |
|---|---|---|
| Intention | What problem you actually want to solve | Build a registrar system, improve the food-delivery experience, handle personal email |
| Specification | What requirements the software must satisfy | Features, interface, data schema, architecture, constraints, correctness criteria |
| Implementation | How to concretely build it | Code, databases, scripts, runnable systems, and deployment environments |
One Intention can correspond to many Specifications; one Specification can also be realized by many Implementations. When the client, the product manager, the analyst, and the programmer end up with different understandings of the same requirement, the gap widens.
Software engineering is the work of continuously filling the gaps between Intention, Specification, and Implementation. Software usually fails not because a line of code has the wrong syntax, but because what was finally implemented was never the thing that was wanted, or because it met the goal while falling short of the specification's requirements for correctness, reliability, and maintainability.
5.2 The QR / Excel case: being able to finish is not the same as doing it right
The class used a QR / Excel tool to show the agent's limits. The task looks clear: input an arbitrary string, encode it, generate a QR-code animation, and use formulas compatible with old versions of Excel.
Without an explicit architecture, the agent tends to inflate the requirement and chase a universal solution "that holds for all inputs". The results can include hard-coding Base64 content into formulas, generating unmaintainable code, or a bare completion only after a long time of repeated patching. Even a runnable result at the end does not mean it satisfies the real Specification, still less that it is fit to keep evolving.
The more reliable method is to limit the problem's scope first, then split the system into layers that can be verified separately:
- First define the minimal input and output that cannot fail;
- Design an intermediate language or DSL;
- Make the intermediate language both executable as Python and translatable into Excel formulas;
- Verify separately whether the Base64 encoding is correct;
- Verify separately whether the generation of every pixel of the QR code is correct;
- Verify separately the translation from the intermediate language to Python and to Excel;
- Form a closed loop with tests, run results, and human review.
This design turns "have the AI directly write the complete program" into "have the AI take part in building the infrastructure, then verify each transformation separately". The code may not be shorter, but the boundaries are clear, errors are easy to localize, and it is easier to maintain.
5.3 A failing project cannot rely on continuing to pile on resources
The classic judgment in The Mythical Man-Month: for a project already mired in failure, adding more people may only make the project fail more. The class extended this judgment to agents: once generated output has produced slop, continuing to invest more tokens does not necessarily change direction, and may even let the wrong structure solidify further.
So when something fails, the first thing to judge is which layer the problem belongs to:
- Whether the requirement was understood correctly;
- Whether the Specification is explicit enough;
- Whether the architecture allows later change;
- Whether the implementation satisfies the specification;
- Whether the tests can discover the errors;
- Whether the current patching is solving the problem, or masking a structural problem.
The goal of software engineering is not to make one demonstration look successful, but to let the system keep working through changing requirements, changing people, changing models, and changing environments. Reliability, the ability to evolve, maintainability, and long-term cost all belong to "whether the software is done right".
6. Human capabilities are still needed in the AI era
Traditional computer education usually starts from the C language, data structures, and concrete implementation, then gradually moves on to software engineering. Students first get familiar with the tools in the implementation space, then learn how to land requirements as programs. Exam questions, meanwhile, often require a definite answer within a very short time.
This training style still has value for foundational learning, but on short-range tasks AI already has more data, stronger memory, and clearer feedback signals. As long as a problem can be defined quickly, tested quickly, and scored quickly, the agent often finishes faster than a person.
The way of learning therefore needs to change: you can let the agent build something first, then go back and review why it works, where it is unreliable, and where the boundaries are. That can be more efficient than hand-writing every detail from scratch, but it carries an obvious risk: the understanding you end up with may only be "it runs" understanding, which is not the same as correct, complete, transferable understanding.
The scarce value of humans
In the framework given in class, human value comes from the following work rather than from finishing a local implementation faster than AI:
- Discovering problems worth solving, instead of only waiting for a clearly defined task;
- Organizing vague intent into a Specification that can be discussed and verified;
- Choosing suitable architectures and intermediate representations to reduce the error between different spaces;
- Judging what results count as success, and what results only pass temporarily;
- Testing, reviewing, and fact-checking the model's output;
- Settling a one-off successful exploration into scripts, Skills, documents, or reusable systems;
- Using cheap experiments to validate direction, and stopping bad directions in time with evidence;
- Taking responsibility for the system's long-term results, risks, and responsibilities.
Curiosity, self-drive, engineering taste, and an understanding of the real world determine whether a person can bring AI to bigger problems. Knowing how to use an agent is only the starting point; knowing what it can and cannot do, and how to organize it into reliable processes, is the core capability of generative software engineering.
7. The conclusions left by the first lecture
The lecture does not present AI as a finished, ultimate tool. Agents keep getting stronger at single tasks, local code, and browser operations, but they still misunderstand requirements, rush to start, chase the short-term reward of "passing the tests", and generate implementations that are hard to maintain. Models may soon learn engineering design and taste, and the methods in this course may quickly become outdated as model capabilities change.
Software engineering does not lose its meaning here. As local execution becomes cheaper and cheaper, direction, structure, verification, and long-term results matter more.
"Old-school programming" is losing its dominant position, but software engineering has not disappeared. Whether a person can be recruited and trusted can no longer be judged only by whether they can write a piece of code that an AI could also write, but by whether they can answer a more difficult question:
Why hire a person, instead of buying a $200 Claude Max?
The answer given in class can be summed up as four things:
- Find problems that are genuinely worth solving;
- Break the problem into experiments with controllable cost;
- Use evidence to stop wrong directions in time;
- Take responsibility for the system's long-term results.
Generative software engineering is about setting direction, filling the gaps between intent and implementation, building verification loops, and turning one-off generated results into systems that can keep evolving.